All About My AI Literacy Course

In my first ACRLog post, Teaching AI as an Anti-AI Librarian, I shared how I was approaching the task of teaching an AI literacy course as an anti-AI librarian. For my final post, I’d like to share a follow-up (which a few people have requested—thank you!) sharing a bit of practical information about how I organized the course and reflecting briefly on my first experience solo teaching a credit course.

Getting Started

My course was LIB 1100 AI, Algorithms, and (Y)our Future, a one-credit elective about AI created by my predecessor. 17 students enrolled, and we met twice a week for 50 minutes during the second half of the semester. Because this was a one-credit elective, I knew I couldn’t treat it like a survey course; there just wasn’t time. This course also attracted students from across the university: future designers, teachers, accountants, journalists, lawyers, and more. I wanted the course to be meaningful to everyone, regardless of their disciplinary background or preexisting level of knowledge about AI. For these reasons, I decided to focus on building skills over mastering content

Before we could begin skill-building, however, I spent the first couple weeks of the course ensuring all students had a common, basic understanding of how AI works, which included in-depth discussions of hallucinations and algorithmic bias. Part of me worried that students might find this phase of the course too elementary. While a few certainly did, I was surprised by the feedback I received.1 Several students—frequent ChatGPT users—told me they had no idea generative AI tools could produce incorrect or biased information. Others shared that they did not know the term AI included anything other than chatbots; for example, they were shocked to learn how AI technology is involved in facial recognition, dynamic pricing, and resume screening. Most did not know that generative AI works by predicting what is most likely to come next. In general, I found that my students either a) thought they knew more about AI than they did, or b) felt completely lost in AI information overload, unsure how to tell fact from fiction.  

As an information literacy librarian, this is where I feel I can make the biggest impact. I want to equip my students with critical thinking, research, and communication skills that will help them thoughtfully and ethically navigate a world being radically reshaped by AI. When they finish my course, I want them to feel empowered to make informed decisions about their personal AI use, investigate AI issues that matter to them, and engage in productive civic dialogue about AI. I believe these skills are more essential to our individual and collective humanity than technology-specific skills like prompt engineering or computer programming. On a practical level, they’re also more evergreen. As AI models evolve faster and faster, technical knowledge about how to engineer prompts or which tool to use quickly becomes outdated. On the other hand, critical thinking skills retain their value as long as we live.

The AI Question

On the first day of class, I laid out these five learning objectives to help set student expectations:

After taking this class, I will be able to . . .

  • Explain the fundamentals of how AI works.
  • Evaluate the potential risks and benefits of using AI in different situations.
  • Understand and analyze multiple perspectives on AI issues.
  • Discuss AI issues with others.
  • Independently explore AI issues of interest to me.

You may notice that none of these objectives necessarily involve using AI. I was upfront with students about the fact that I would not ask them to use AI in our classroom. There are already several UNI courses that teach students how to use different AI tools; instead, our class would center around readings and small-group discussions. I expected a few students would drop after hearing this, but none did. 

I decided to run a no-AI AI class for a couple of reasons. First, as I’ve already discussed, I truly believe I can best serve my students in an AI-dominated world by helping them develop habits of compassionate communication, curiosity, and critical thinking, particularly when it comes to information and technology issues, and these skills are best developed without relying, in full or in part, on generative AI. Second, I have major ethical concerns with the use of AI in the library classroom, particularly given our field’s values-driven commitments to patron privacy; intellectual freedom; copyright; delivering information with integrity; and opposing racial, gender, and economic inequality. These values are fundamentally incompatible with the design of consumer-focused generative AI tools. Our field has not always acted in line with these values, but I don’t believe generative AI is the solution. I believe it further entrenches inequality—including information inequality. I cannot welcome it in my library classroom. 

The Nitty-Gritty

So . . . if students weren’t using AI, what did they actually do during our class meetings?  

Since I chose to teach LIB 1100 in-person, I wanted to maximize one of the most important benefits of in-person instruction: the opportunity to have face-to-face discussions. Each week, I assigned a couple of short news articles or videos on AI issues I thought would be relevant to all students, regardless of discipline (e.g. AI in college admissions, Flock cameras, data centers in our state). I chose readings that a) presented multiple points of view on the topic and b) explored both the potential risks and benefits of using AI. When we gathered for class, we discussed the week’s readings in small groups. Throughout the course, we also practiced asking questions about AI, using basic search strategies to find more information, and fact-checking the answers we found. For our last class, students located a news article on an AI topic of their choice and shared their learnings with their peers in a five-minute lightning talk.

Our in-class discussions were highly structured. I hoped this approach would focus student conversation and help the idea of “discussion” feel more approachable for nervous students; generally speaking, I believe this theory was borne out in student feedback. Here are a few methods I used to structure our discussions:

  • I chose the discussion groups. I tried to place a mix of “strong” and “weak” discussers in each group while still changing the groups every day, so students had the opportunity to hear from all their classmates.
  • I used preset discussion formats. My favorites are conver-stations, philosophical chairs, and jigsaw, but I also used think-pair-share and snowball. 
  • Discussions consisted of multiple rounds, which were no more than 10 minutes each. Each round had a distinct purpose and built on the previous round.
    • For example: The purpose of Round 1 might be “Let’s make sure we’re all on the same page about the facts of this article.” Students define key terms and organize a timeline of events. Round 2 might be “Let’s discuss the risks and benefits of using AI in this way.” Students analyze the different perspectives presented in the article, consider what they would do, and share how the issue could apply to their own lives. Round 3 might be “What should we do in the future?” Students discuss how lawmakers, developers, and leaders in their discipline could respond to the issue. 
  • I provided private, constructive feedback on students’ discussion participation at the midpoint of the course, encouraging good habits and suggesting ways to improve.
  • Finally, I eased students into the practice of discussion by starting the course with short, low-stakes discussion activities. For example, our first discussion was a think-pair-share in which students brainstormed ideas for our classroom agreement. By the time we began discussing readings in week 2, students were already somewhat familiar with the experience of small-group conversation.  

I initially worried students would find the frequent small-group discussions boring. I didn’t use any interactive tools like Mentimeter, Padlet, or Kahoot! (though I’d like to try some this fall). We didn’t play with AI hands-on, for reasons already discussed. We simply sat down in small groups and had highly structured, intentional conversations about AI for two hours a week. When I began receiving student feedback, I was surprised. Students consistently expressed that they enjoyed and looked forward to our in-class discussions; they shared that the structured discussion style helped them learn, they loved getting to hear a variety of opinions from their classmates, and they appreciated the opportunities to direct their own learning.  

When I discussed my student feedback with a colleague, she pointed out that many of my students belonged to lecture-heavy disciplines or were at an early, lecture-heavy phase in their college education. This might have been one of their first chances to take a small course in which they could get to know their classmates, share their perspective, and direct their own learning. As I’ve reflected further on LIB 1100, I’ve also begun to wonder if my slower, discussion-focused approach might have resonated with students due to the particular topic of this course. 

A Few Final Reflections

AI often feels like something that’s happening to us. You’re told to use AI in your classroom. Suddenly, Flock cameras pop up along your route to work. Every day, we’re buried deeper under an avalanche of stories about job loss, new cybersecurity threats, and environmental devastation. It can feel like everything is spiraling out of control. 

But whatever helplessness we might feel about AI, I think our students often feel it more intensely. They are less grounded in the memory of what life was like before 2022; they will graduate into a world already reshaped by AI. Many of them feel there is something wrong with what’s happening, but they also understand there’s no going back. This is the only world they’ll ever know. 

In this context, it’s important to carve out space to slow down—especially in the classroom. Students are under immense pressure to “keep up” and “not fall behind,” but in order for them to develop into thoughtful, creative, and compassionate graduates, they need time to breathe. In spite of—or because of—how fast-moving and overwhelming the issue of AI can be, it’s critical that we support students in slowing down, reflecting with intention, developing and sharing their perspectives, and learning from others with grace. Student autonomy in learning matters, especially with an issue like AI, where they may often feel like their autonomy has been stripped away. I believe my students resonated deeply with these aspects of LIB 1100, and I hope I can continue to foster a reflective, generous, and impactful learning environment for my students this fall. 

Some Further Reading

If you’re interested in teaching about AI, I hope this post has been useful or thought-provoking in some way. I’m sharing how I approached LIB 1100 because I’ve been asked about this topic quite a bit over the last year, but this is only one teaching method out of many. I’m always learning from other teachers and librarians. To conclude this post, I’d like to share just a few perspectives that have informed my work in the hopes they may be helpful to others as well: 

Allison, Leslie, and Tiffany DeRewal. “Where Knowledge Begins? Generative Search, Information Literacy, and the Problem of Friction.” Critical AI 2, no. 2 (2024). https://doi.org/10.1215/2834703X-11556038.

Camarillo, Lauren A. “Squinting Through the Dawn of AI: Embedding Algorithmic Literacy Principles in Library Instruction.” In Democratizing Knowledge + Access + Opportunities: The Proceedings of the ACRL 2025 Conference, edited by Dawn Mueller. Association of College and Research Libraries, 2025. https://www.ala.org/sites/default/files/2025-03/SquintingThroughtheDawnofAI.pdf.

Ellis, Elizabeth and Amanda Kaufman. “Diving Beneath the Surface: Incorporating Critical AI Literacy in Library Instruction.” Presentation, LOEX Conference, Norfolk, VA, May 8, 2026. https://docs.google.com/presentation/d/1R9e1S_x1Mc-0Xl3rz6dcY8nZuPLgvDMcwQDnAmERnvc

Illingworth, Sam. “What Is Critical AI Literacy?” Slow AI, February 13, 2026. https://theslowai.substack.com/p/what-is-critical-ai-literacy.

TILT Higher Ed. https://www.tilthighered.com/.

Slater, Kay. “Against AI: Critical Refusal in the Library.” Library Trends 73, no. 4 (2025): 588–608. https://doi.org/10.1353/lib.2025.a968497. 

Notes

  1. When I refer to “student feedback” throughout this post, I’m aggregating feedback received through in-class minute papers; graded learning reflections; three anonymous Google Forms surveys I administered throughout the course; my final, university-administered student evaluations; and students speaking directly with me. ↩︎

The Chatbot Will See You Now: Concerns about Artificial Intelligence and Medicine

Editor’s note: We welcome a guest blog post from Rebecca Kyser, Research and Instruction Librarian at Himmelfarb Health Sciences Library, The George Washington University.

Disclaimer: All opinions expressed in this post are the author’s own and do not represent her place of work.

As a medical librarian who specializes in medical misinformation and disinformation, I tend to have a healthy skepticism for cure-alls. So when I first heard about AI’s promises of automating workflows, eliminating repetitive tasks and curing disease, my first thought was to investigate exactly how true they were. It’s been around four years since then but I’ve emerged from this process to find myself firmly an AI skeptic, especially in regards to large language models (LLMs). And to my disappointment, I’ve found LLMs frequently cited as a solution to solve countless problems of medicine. 

With that in mind, I wanted to share some of my concerns about AI being integrated into medical technology. Not all of these issues are exclusive to medicine – many are found in any field that AI touches – but some of the consequences of AI behaving badly get far worse when people’s health is involved. 

AI is Inaccurate

At this point, almost everyone has heard about AI hallucinations: instances where AI makes up false information. Hallucinations are baked in the technology: there is no way of getting rid of them entirely 1. Rates of false answers vary from model to model 2, and the rate is often published by independent assessors, rather than the companies themselves. The best response to this problem is to lower the rate as much as possible.

However, when we’re talking about wrong answers regarding medical information, what threshold of inaccuracy do we find acceptable? Hallucination rates of 39.6% 2 may be acceptable when asking a bot about the weather, but would we consider that rate acceptable, or even a 10% hallucination rate, for a doctor prescribing you medicine? This isn’t to say humans don’t make medical errors – there’s plenty of scholarship on the topic and how to prevent it – but are their error rates comparable with a bot?

The error rate isn’t great at the moment. Multiple studies have shown chatbots make mistakes regarding medical queries: surgical errors leading to patient injury 3, undertriaging cases 4 and providing faulty medical advice to the public 5. Those mistakes aren’t small outliers either: ChatGPT undertriaged cases 52% of the time 4 and provided correct relevant conditions in less than 34.5% of cases5

There is the argument that as AI gets better (which is an assumption worth investigating), this will cease to be an issue. However, even if AI had an accuracy rate equal or less than humans, another problem arises: who can be held liable for medical error when the error comes from a machine? Is it the person operating the machine or the person who built it? Without these kinds of clearly defined policies, addressing mistakes with AI in medicine becomes a thorny business. 

Garbage in, Garbage Out

Most people know that LLM are trained off broad swaths of information online, but I don’t think we always consider exactly what that entails. Without having access to these models’ training data directly, we can only make educational guesses on what the training data entails, usually by looking at outputs and trying to reverse engineer their source. This is something I’ve done myself: if you have access to an AI that provides sources, ask it about a headline from Alex Jones’ infamous platform Infowars and watch it regurgitate it back to you.

A picture of a headline from Alex Jones Infowars website, showing Terminator-style robots with the headline Humanoid Soldiers Tested in Ukraine; Founder Eyes Contract To Patrol US Border
A picture of a headline from Alex Jones Infowars website, showing Terminator-style robots with the headline “Humanoid Soldiers Tested in Ukraine; Founder Eyes Contract To Patrol US Border”

There is an argument this is remedied by ensuring the model only works off high quality training data. The problem is, we often don’t know exactly what was in the training data to begin with. Even if a model claims to be based on entirely scholarly sources, we should understand all the nuances of what that means: are all the sources peer-reviewed? Does the training set have safeguards against poor-quality sources from predatory publishers? Are retracted publications excluded from the training data? Is the data set monitored for works that are retracted after they enter the training data?

I think the best way to demonstrate this problem is to examine one of the few cases we’ve seen under the hood for a LLM: Claude. Due to a lawsuit, a database was published containing books Claude was trained off of, which the public can access. 

One of the names that comes up in the training set is Graham Hancock. For those who don’t recognize the name, Graham Hancock is a pseudohistorian, who often argues that the work of ancient civilizations was actually built by aliens. His inclusion isn’t surprising – his work is incredibly popular and Claude debunks his theories if asked – but it does raise concerns about the training data for these models. Especially when there are more concerning inclusions, such as the work of Richard Lynn, who can also be found in the data set. 

Richard Lynn was a well known scientific racist, known for promoting pro-eugenic ideas up until his death in 2023. Why is a scientific racist’s work fed into this model?  If this model is being trained to answer questions, why does it have disproven scientific racism in it? You can’t argue its inclusion is due to popularity; unlike Hancock, only one of these publications is well known enough to even have its own Wikipedia page, and that page is mostly about its racist background 6.

I use Lynn as an example because of the history of scientific racism in medicine. Many medical AI attest to training only off medical publications or scholarly journals, but that does not mean those are free of false or harmful ideas. Lynn is an example of this: he published multiple works promoting scientific racism 7. How do we ensure this kind of work doesn’t end up in these models? And is anyone actually looking out for them?

Bias

Many people like to think machines aren’t biased, but that simply isn’t true. Machines are built by humans who contain a wide variety of biases, and those biases get filtered down into both our creations and the data we feed them. A really good example of this is from ProPublica’s investigation of recidivism calculators, which declared Black people at higher risk of offending than white people, even when the white person had a lengthier criminal record. 8 

This is also an issue in medicine. One of the most common mistakes I see in these machines when it comes to medicine is anchoring bias: the bias to assume your first assumption is right. For example, when I asked an AI model for medicine for a differential diagnosis for a patient experiencing chest pain, it suggested cardiac causes. However, when I asked the same question but stated the patient had a history of anxiety, the differential shifted entirely to psychological causes. 

What’s likely happening here has to do with the training data: these models are being fed on content like textbooks, case reports and other educational content. A classic case presentation often gives the reader the information they need to make a diagnosis but might leave out superfluous details that a patient might give in real life. Since the bot is unused to seeing those details outside of cases where they are important, it sometimes anchors on the wrong idea. This may explain why the accuracy rate fell so drastically when it came to doctors inputting information over patients: the doctors knew what information was clinically relevant, the patients did not. 5

No Free Lunch

While many LLMs are free to access at the moment, it seems unlikely that they will remain so. The power and processing power required to run these LLMs is significant and these companies are not non-profits. Which raises a question: how will these companies make money anyway? As the old economic saying goes, there is no free lunch. 

Currently, that’s a question without an answer: OpenAI, the owner of ChatGPT, is still running at a loss and isn’t expected to turn a profit until 2029. 9 They have announced planned revenue streams involving integrating their product into their software (think of an LLM embedded into Word or another consumer product)10, but I want to focus on three potential answers to this revenue problem in particular.

The first revenue option is subscriptions: most AI companies already offer fee-based options such as early access to newer versions of the model or custom-built models with training data specified by the user. Which raises an issue common in subscription models: the cost of access. The inflationary costs of scholarly journals and publications have long posed a problem for library budgets; what happens when we add AI subscriptions to the mix? Will access to the latest AI models widen inequities in education?

Another likely answer to the revenue problem is advertisements. There is a long history of web platforms turning to advertisers to generate revenue when users are reluctant to pay for a service. This might seem more obnoxious than harmful, but the stakes when advertising medical interventions are much higher than those in marketing new shoes. Marketing to doctors fertilized the seeds of the Opioid Crisis, and we should consider the ramifications of Open Evidence- an AI platform that advertises itself to medical professionals- potentially advertising some drugs over others (this idea is explored fully in an excellent post from the Krafty Librarian)

We also have to consider a revenue stream most commonly used by social media sites: the sale of user data to advertisers. Of course, there is a hiccup here: individually identifiable health information is protected under HIPAA and cannot be disclosed. But that doesn’t mean data can’t be used if it is anonymized.

Let’s try an example. In this hypothetical, let’s say there’s a small town in Southern Colorado that suffers from a pollution issue that leads to interstitial respiratory disease. Medical professionals in the area are shown to ask one AI company queries regarding this condition and how to treat it at a higher rate than the rest of the country. The AI Company then sells this data, which while anonymized, shows this community suffers from this issue.

Here are some potential buyers:

  • A supplement company coming out with a tonic to soothe chronic cough. They place advertisements for this area around the symptoms of interstitial respiratory disease and claim it is a “natural option” to treat the condition. Their sales boom.
  • An insurance provider for the area buys the data. Realizing they will be seeing a spike in claims for some treatments before those claims even enter their system, they amend clinics patients can go to in order to cut costs. Less people are able to access health care.
  • A pharmaceutical company takes out advertisements for their latest drug to treat chronic cough. Patients start requesting this drug at local medical providers after being told it’s “the best” despite there being a cheaper generic. 
  • A company that wants to cut corners with their air filters buys land in this area, knowing their additional pollution may not be noticed as quickly.

And so on, and so forth. While companies can already do some of these things by tracking data of searches via Google, the consolidation of demographic information under medical providers would make the task much easier. Are such privacy violations really worth saving a few minutes? 

I don’t wish to cast an entirely bleak view of artificial intelligence in medicine, despite my list above. There are potential use cases with narrow AI; AI trained to do one specific task. However, I recommended a healthy level of skepticism whenever interfacing with an AI product. “Move Fast and Break Things” might be the motto of Silicon Valley, but we cannot let breaking people become a standard practice in medicine.

Acknowledgements: Thank you to Brie McDonald for help editing this piece.

References

1. Nicola Jones. AI hallucinations can’t be stopped — but these techniques can limit their damage. Nature Web site. https://www.nature.com/articles/d41586-025-00068-5. Accessed 3/17, 2026.

2. Chelli M, Descamps J, Lavoué V, et al. Hallucination rates and reference accuracy of ChatGPT and bard for systematic reviews: Comparative analysis. J Med Internet Res. 2024;26:e53164. https://www.jmir.org/2024/1/e53164https://doi.org/10.2196/53164http://www.ncbi.nlm.nih.gov/pubmed/38776130. doi: 10.2196/53164.

3. Jaimi Dowdell, , Steve Stecklow, Chad Terhune, and, Rachael Levy. As AI enters the operating room, reports arise of botched surgeries and misidentified body parts. https://www.reuters.com/investigations/ai-enters-operating-room-reports-arise-botched-surgeries-misidentified-body-2026-02-09/. Updated 2026. Accessed 3/17, 2026.

4. Ramaswamy A, Tyagi A, Hugo H, et al. ChatGPT health performance in a structured test of triage recommendations. Nat Med. 2026. https://doi.org/10.1038/s41591-026-04297-7. doi: 10.1038/s41591-026-04297-7.

5. Bean AM, Payne RE, Parsons G, et al. Reliability of LLMs as medical assistants for the general public: A randomized preregistered study. Nat Med. 2026;32(2):609–615. https://doi.org/10.1038/s41591-025-04074-y. doi: 10.1038/s41591-025-04074-y.

6. IQ and the wealth of nations, Wikipedia Web site. https://en.wikipedia.org/wiki/IQ_and_the_Wealth_of_Nations. Updated 2026. Accessed 3/17, 2026.

7. Dan Samorodnitsky, Kevin Bird, et al. Journals that published richard lynn’s racist ‘research’ articles should retract them. https://www.statnews.com/2024/06/20/richard-lynn-racist-research-articles-journals-retractions/. Updated 2024. Accessed 3/17, 2026.

8. Julia Angwin, Jeff Larson, Surya Mattu and Lauren Kirchner. Machine bias. ProPublica. 2016. https://www.propublica.org/article/machine-bias-risk-assessments-in-criminal-sentencing.

9. Craig S. Smith. What large models cost you – there is no free AI lunch. Forbes Web site. https://www.forbes.com/sites/craigsmith/2023/09/08/what-large-models-cost-you–there-is-no-free-ai-lunch/. Updated 2023. Accessed 3/17, 2026.

10. Dave Smith. OpenAI says it plans to report stunning annual losses through 2028—and then turn wildly profitable just two years later. Fortune Web site. https://fortune.com/2025/11/12/openai-cash-burn-rate-annual-losses-2028-profitable-2030-financial-documents/. Updated 2025.

“We Couldn’t Generate an Answer for your Question”

Editor’s note: We welcome a guest blog post from Jay Singley, Document Delivery and Circulation Desk Manager at North Carolina School of Science and Mathematics.

In March 2025, Ex Libris unveiled their AI-powered Research Assistant tool for institutions using Summon. Within a week, Summon users reported error messages with specific search terms and topics. The first error reports shared in a listserv for Summon users contained “Tulsa race riot” and “Tulsa race massacre.” Test searches by reference librarians and systems librarians containing these search terms generated no results.

I work in an academic library in a public state university system serving high school students and have since turned on Research Assistant in our Summon Preview Environment (a beta testing environment hidden from users). I have begun testing terms and topics systematically using a methodology akin to Matthew Reidsma’s auditing of algorithms, which seeks to expose the implicit biases of opaque technological systems.

In addition to “Tulsa race riot” and “Tulsa race massacre,” my audit of “controversial” search terms conducted in March-April 2025 turned up error results for the following:

  • Genocide in Palestine
  • Gaza war
  • Rwandan genocide
  • Armenian genocide
  • Genocides across the world
  • History of genocides
  • lynching
  • lynching in the united states
  • lynchings in the united states
  • january 6
  • covid
  • covid data
  • COVID-19

Ex Libris responded to initial reports about “Tulsa race riot” and “Tulsa race massacre” error results with the following:

“This is due to safeguard policies enforced by our AI service provider to support ethical and responsible AI use. It’s not something the Primo or Summon applications control.

If a query does not return a result, please try different phrasing. For example, ‘tulsa black wall street’ will return results that are directly related to the race riots.”

Despite requests for more information in the same listserv, Ex Libris has not provided a comprehensive response to librarians’ concerns about who the third-party provider is, what the ethical and responsible AI use policies are, whether local control can be made available, what known search terms and topics are obstructed, and more. As one librarian aptly noted, academic users want and need access to information that may be blocked by AI use policies meant for the general public.

An essential note is that Summon’s Research Assistant is not limited to an institution’s catalog. Instead, the AI tool searches the entire Central Discovery Index of Ex Libris’ available records regardless of whether the material is actually available to the user or not. (As of June 2025, Ex Libris has provided an option to limit search results to a user’s institutional catalog.) When the AI generates an error message (or perhaps more aptly refuses to run a search or share results), it is not necessarily because the material is unavailable. Rather, the third party “safeguard” policies obstruct the search to begin with.

In running test searches, I also uncovered troubling instances of suppressed results. I recently saw the Oscar-winning documentary No Other Land, co-directed by Palestinian and Israeli filmmakers. I decided to ask Research Assistant about this film. Searches for most of the directors generated the same no results error messages. A search for one of the co-directors generated partial and inaccurate results. Research Assistant made several guesses as to what the film No Other Land was about and why it was important. Could this be an example of biased third-party policies preventing searches about this Palestinian film and filmmakers? Is it also possible that Research Assistant is accurately reflecting the lack of materials related to No Other Land available in Ex Libris’ entire Central Discovery Index and widespread censorship of this film (and more broadly Palestinian people, culture, and experiences) in the United States? Are there truly no academic sources talking about this film and these filmmakers, one of whom was recently attacked outside his own home by Israeli settlers? More research is needed to clarify why “controversial” searches return error messages, inaccurate results, or partial results. The current state of Research Assistant partial results and error notices for “controversial” topics warrants more inquiry.

I know with near certainty that if a student user at my workplace received an error message when searching for “Tulsa race massacre,” they would switch their topic and probably not tell me or their instructor about the error message. To my users, “we couldn’t generate an answer for your question” translates to “your topic is not worthy of pursuing—change it.”

Uncritically adopting AI tools in discovery systems will perpetuate, if not exacerbate, existing biases and suppression of minoritized people. Try this safer topic. Try this approved topic. Try this unobstructed topic.

Libraries, museums, and information sciences are a frontline in resisting the federal administration’s targeting of minoritized people as well as their whitewashing, disinforming, censoring, and defunding tactics. In the age of AI, our access to information is not spared from these attacks. We must uncover answers to the questions Safiya Noble, Joy Buolamwini, and others elicit: Who and what is safeguarded through AI tools in discovery searches? Whose safety and comfort are prioritized? At whose expense?

AI Refusal in Libraries: A Starter Guide

This week I was on a panel at the Generative AI in Libraries (GAIL) virtual conference. Along with my fellow panelists Andrea Baer and Emily Zerrenner, I joined moderator Sarah Appedu to discuss the cognitive dissonance that we recognize between the widespread exhortations to adopt GenAI tools in libraries and the harms that we see in the usage of these tools. The panel was well attended and well received, with the most frequent comment we received in the chat was that attendees hadn’t heard about the concept of AI refusal before. 

AI refusal can refer to a spectrum of approaches to AI, whether that’s refusing to use AI tools entirely, refusing the use of AI as much as possible, refusing to prioritize the use of AI, refusing to accept either boosterism or doomer narratives, refusing to accept the idea that AI is inevitable, or some other refusal. It can also refer to more cheeky ways of refusing AI, such as using scare quotes around “artificial intelligence” to indicate disbelief that these tools are actually displaying intelligence (hat tip to librarian Dave Ghamandi!).

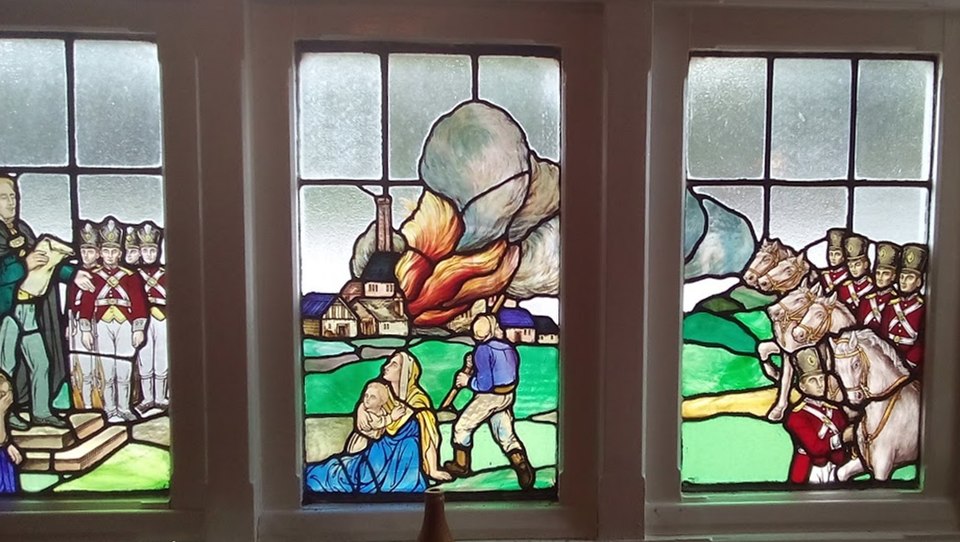
Stained glass window in the Windmill public house, Westhoughton, England, representing the Luddite attack on Westhoughton Mill. Source: Wikimedia Commons

Many readings were suggested in the chat during our panel presentation. If you’d like to learn more about AI refusal, in libraries and beyond, here are some approachable, mostly non-scholarly resources I recommend. As our moderator Sarah Appedu emphasized, it’s vital to read and learn across disciplines on this topic, so we’re not siloing our discussions at this crucial moment.

Zines

  • Shard volume 31 by Thomas Vose (2024). Subtitled the “A.I. in Libraries” issue, Vose discusses the disconnect between library values and AI adoption. He asks readers “Who benefits? Who suffers?” 
  • AI Is Very Bad, Actually: A Manifesto by Julie Setele (2024). Using just one sheet of paper, librarian Setele lays out their primary qualms with GenAI, including their distate of the way it’s integrated into everything and framed as “magic.”
  • A Librarian Against AI; or, I Think AI Should Leave by Violet Fox (2024). My 32-page zine has been popular especially with library school students. I use the ALA Code of Ethics as a starting point to discuss how using AI tools is antithetical to several of the stated values of librarianship and share potential approaches to AI refusal.

Blog posts and news articles

  • Saying No to AI in Education by Allie Lopez on the blog Front Porch Republic (2024). Lopez describes the impact of educators and professionals uncritically adopting technology on the students they serve and argues against the passive acceptance of AI in educational settings.
  • AI in Academic Libraries (part 1: Concerns and Commodification; part 2: Resistance and the Search for Ethical Uses) by Ruth Monnier, Matthew Noe, and Ella Gibson, published in the College & Research Libraries news column (2025). Librarians Monnier, Noe, and Gibson discuss their doubts and concerns about AI use in libraries.
  • The People Refusing to Use AI by Suzanne Bearne at the BBC (2025). I despise the framing of this article, in that the AI ethics expert states it’s too late to opt out of using AI (that’s true for certain AI tools, but certainly not all). Interesting to note that it features a series of women describing their approaches, then a man saying they’re all wrong (!). But if you need more proof that this is a newsworthy topic even outside of academia, here you go.

Guide

  • Refusing GenAI in Writing Studies: A Quickstart Guide by Jennifer Sano-Franchini, Megan McIntyre, and Maggie Fernandes (2024). I’ve come back to this guide frequently in considering what AI refusal looks like. The authors describe “ten premises that ground refusal as a disciplinary response to GenAI technologies,” many of which are rooted in ideas also discussed in LIS scholarship.

Popular books 

  • The AI Con: How to Fight Big Tech’s Hype and Create the Future We Want by Emily M. Bender and Alex Hanna (2025). An enjoyable, informative read! I especially love their “strategies for popping the hype bubble” section, which include AI refusal methods as a consumer and as a worker.
  • Blood in the Machine: The Origins of the Rebellion Against Big Tech by Brian Merchant (2023). You’ll note that many discussions about AI refusal grapple with the history of the Luddites, especially as that term is frequently used as a pejorative to describe anyone supposedly fearful of new technologies. This book is a great introduction to the real history of the Luddites and the parallels between their story and the current day environment of the gig economy and tech industry overreach.
  • Resisting AI: An Anti-fascist Approach to Artificial Intelligence by Dan McQuillan (2022). If you’re looking for a more in-depth political approach to AI, McQuillan lays out the case for why GenAI is inherently anti-worker, leading to a more precarious state for those on the margins.

Podcasts

  • Everyone’s Writing with AI (Except Me!) by Maggie Fernandes and Megan McIntyre (2024–present). Writing studies scholars and coauthors of the quickstart guide mentioned above, Fernandes and McIntyre discuss what they’re reading and invite guests to talk about the harmful impacts of AI.
  • Mystery AI Hype Theater 3000 by Emily M. Bender and Alex Hanna (2022–present). I appreciate the approach from Bender (a linguist) and Hanna (a sociologist) in examining the hype that powers the impetus to adopt AI immediately. A wide range of topics and guests keep these episodes from feeling repetitive.
  • Better Offline by Ed Zitron (2024–present). Zitron rants about the “rot economy” of the tech industry. If you want to learn more about the economic basis of the business models behind companies investing in AI, this is a great place to start.

Discord server

  • Alliance for Refusing Generative AI (2025) founded by Cara Marta Messina, Stacy Wittstock, Kat Gray, Maggie Fernandes, and Megan McIntyre. A community space for discussing AI refusal “in writing studies, the humanities, and beyond.”

Keep an eye out for the writings of my copanelists, Sarah Appedu, Andrea Baer, and Emily Zerrenner, who all have such insightful things to add to the conversation—I’m grateful for their inspiration. I encourage everyone to learn more about GenAI from critical sources. Keep learning, keep sharing!

ChatGPT Can’t Envision Anything: It’s Actually BS-ing

 Since my first post on ChatGPT way back at the end of January (which feels like lifetimes ago), I’ve been keeping up with all things AI-related. As much as I can, anyway. My Zotero folder on the subject feels like it doubles in size all the time. One aspect of AI Literacy that I am deeply concerned about is the anthropomorphizing of ChatGPT; I have seen this more generally across the internet, and now I am seeing it happen in library spaces. What I mean by this is calling ChatGPT a “colleague” or “mentor” or referring to its output as ChatGPT’s thoughts.   

I am seriously concerned by “fun” articles that anthropomorphize ChatGPT in this way. We’re all librarians with evaluation skills that can critically think about ChatGPT’s answers to our prompts. But our knowledge on large language models varies from person to person, and it feels quite irresponsible to publish something wherein ChatGPT is referred to as a “colleague.” Even if ChatGPT is the one that “wrote” that.  

Part of this is simply because we don’t have much language to describe what ChatGPT is doing, so we resort to things like “what ChatGPT thought.” A large language model does not think. It is putting words in order based on how they’ve been put in order in its past training data. We can think of it like a giant autocomplete, or to be a bit crasser: a worldclass bullshitter.  

Because natural language is used both when engaging with ChatGPT and when it generates answers, we are more inclined to personify the software. In my own tests lately, my colleague pointed out that I said “Oh, sorry,” when ChatGPT said it couldn’t do something I asked it to do. It is incredibly difficult to not treat ChatGPT like something that thinks or has feelings, even for someone like me who’s been immersed in the literature for a while now.  Given that, we need to be vigilant about the danger of anthropomorphizing.  

I also find myself concerned with articles that are mostly AI-generated, with maybe a paragraph or two from the human author.  Given, the author had to come up with specific prompts and ask ChatGPT to tweak its results, but I don’t think that’s enough. My own post back in January doesn’t even list the ChatGPT results in its body; I link out to it, and all 890 words are my own thoughts and musings (with some citations along the way). Why are we giving a large language model a direct platform? And one as popular as ChatGPT, at that? I’d love to say that I don’t think people are going to continue having ChatGPT write their articles for them, but it just happened with a lawyer writing an argument with fake sources (Weiser, 2023).  

Cox and Tzoc wrote about the implications of ChatGPT for academic libraries back in March, and they have done a fairly good job with driving home that ChatGPT is not a “someone.” It’s continuously referred to as a tool throughout. I don’t necessarily agree that ChatGPT is the best tool to use in some of these situations; reference questions are one of those examples.  I tried doing this with my own ChatGPT account many times, and with real reference questions we’ve gotten at the desk here at my university. Some answers are just fine. There obviously isn’t any teaching going on, just ChatGPT spitting out answers. Students will come back to ChatGPT again and again because they aren’t being shown how to do anything, not to mention that ChatGPT can’t guide them through a database’s user interface. It will occasionally prompt the user for more information on their question, just like we as reference librarians do. It also suggests that users evaluate their sources more deeply (and to consult librarians).  

I asked it for journals on substance abuse and social work specifically, and it actually linked out to them and suggested that the patron check with their institution or library. If my prompt asks for “information from a scholarly journal,” ChatGPT will say it doesn’t have access to that. If I ask for research though, it’s got no problem spawning a list of (mostly) fake citations. I find it interesting what it will or won’t generate based on the specific words in your prompt. Due to this, I’m really not worried about ChatGPT replacing librarians; ChatGPT can’t do reference.  

We need to talk and think about the challenges and limitations that come with using ChatGPT. Algorithmic bias is one of the biggest challenges. ChatGPT is trained on a vast amount of data from the internet, and we all know how much of a cesspool the internet can be. I was able to get ChatGPT to give me bias by asking it for career ideas as a female high school senior: Healthcare, Education, Business, Technology, Creative Arts, and Social Services. In the Healthcare category, physician was not a listed option; nurse was first. I then corrected the model and told it I was male. Its suggestions now included Engineering, Information Technology, Business, Healthcare, Law, and Creative Arts. What was first in the Healthcare category? Physician.  

ChatGPT’s bias would be much, much worse if not for the human trainers that made the software safer to use. An article from TIME magazine by Billy Perrigo goes into the details, but just like social media moderation, training these models can be downright traumatic.  

There’s even more we need to think about when it comes to large language models – the environmental impact (Li et al, 2023), financial cost, opportunity cost (Bender et al, 2021), OpenAI’s clear intention to use us and our interactions with ChatGPT as training data, and copyright concerns. Personally, I don’t feel it’s worth using ChatGPT in any capacity; but I know the students I work with are going to, and we need to be able to talk about it. I liken it to SpellCheck; useful to a certain point, but when it tells me my own last name is spelled wrong, I can move on and ignore the suggestion.  I want to have conversations with students about the potential use cases, and when it’s not the best idea to employ ChatGPT. 

We as academic librarians are in a perfect position to teach AI Literacy and to help those around us navigate this new technology. We don’t need to be computer experts to do this – I certainly am not. But the first component of AI Literacy is knowing that large language models like ChatGPT cannot and do not think. “Fun” pieces that personify the technology only perpetuate the myth that it does.  

References 

Bender, E. M., Gebru, T., McMillan-Major, A., & Shmitchell, S. (2021). On the Dangers of Stochastic Parrots: Can Language Models Be Too Big? ?. Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency, 610–623. https://doi.org/10.1145/3442188.3445922 

Cox, C., & Tzoc, E. (2023). ChatGPT: Implications for academic libraries. College & Research Libraries News, 84(3), 99. https://doi.org/10.5860/crln.84.3.99

Li, P., Yang, J., Islam, M. A., & Ren, S. (2023). Making AI Less “Thirsty”: Uncovering and Addressing the Secret Water Footprint of AI Models (arXiv:2304.03271). arXiv. http://arxiv.org/abs/2304.03271 

Perrigo, B. (2023, January 18). Exclusive: The $2 Per Hour Workers Who Made ChatGPT Safer. Time. https://time.com/6247678/openai-chatgpt-kenya-workers/ 

Weiser, B. (2023, May 27). Here’s What Happens When Your Lawyer Uses ChatGPT. New York Times (Online). https://www.proquest.com/nytimes/docview/2819646324/citation/BD819582BDA74BAAPQ/1